Introduction: Why Live Translation Still Falters
Picture a cross-border town hall: five languages, a tight agenda, and a camera crew waiting on the signal. The interpretation system must create a clear audio path for every listener, in real time, without fail (no excuses). In many post-event reports, over a third of attendees flag audio issues—dropped channels, muddy speech, or long delays. If reliability and clarity are this fragile, what exactly is going wrong, and how do we fix it for good? A robust simultaneous interpretation system promises low latency and clean separation of languages, but practice often lags the promise. We need to break down the entire chain—microphone, codec, DSP, and distribution—to see where the cracks form. Then we can compare options with a clear head (and a clear signal). Here is the baseline we will use, and why it matters for scale.
Hidden Fault Lines in Traditional Solutions
Where do legacy setups break?
Legacy systems often hinge on a few weak links: mixed analog signal paths, uneven gain structure, and fragile distribution. Small issues stack up fast. Channel crosstalk slips in when shielding is poor or when the rack layout is tight. RF interference creeps into wireless inputs, raising the noise floor before interpreters even hear the feed. Then the digital side adds its own tax. A heavy codec or a slow DSP chain inflates the latency budget—listeners feel a half-beat behind the speaker, which erodes comprehension. Look, it’s simpler than you think: bad in equals bad out, and every hop adds risk. Redundancy is also thin; single power converters or non-redundant network switches mean one blip can mute hundreds.
There is a deeper, hidden pain point: control. Teams rarely have clear telemetry for packet jitter, input clipping, or infrared emitter coverage. They hear “it sounds off,” yet cannot pinpoint whether the fault lies in IR transmission, network QoS, or booth audio. Without event-level observability—per-channel meters, error logs, and alerts—operators overcorrect or underreact. Consequence: fatigue for interpreters, higher cognitive load, and uneven delivery. And—funny how that works, right?—audiences then blame “translation quality” when the structure underneath was the culprit.
Comparative Horizon: Principles and Practical Paths
What’s Next
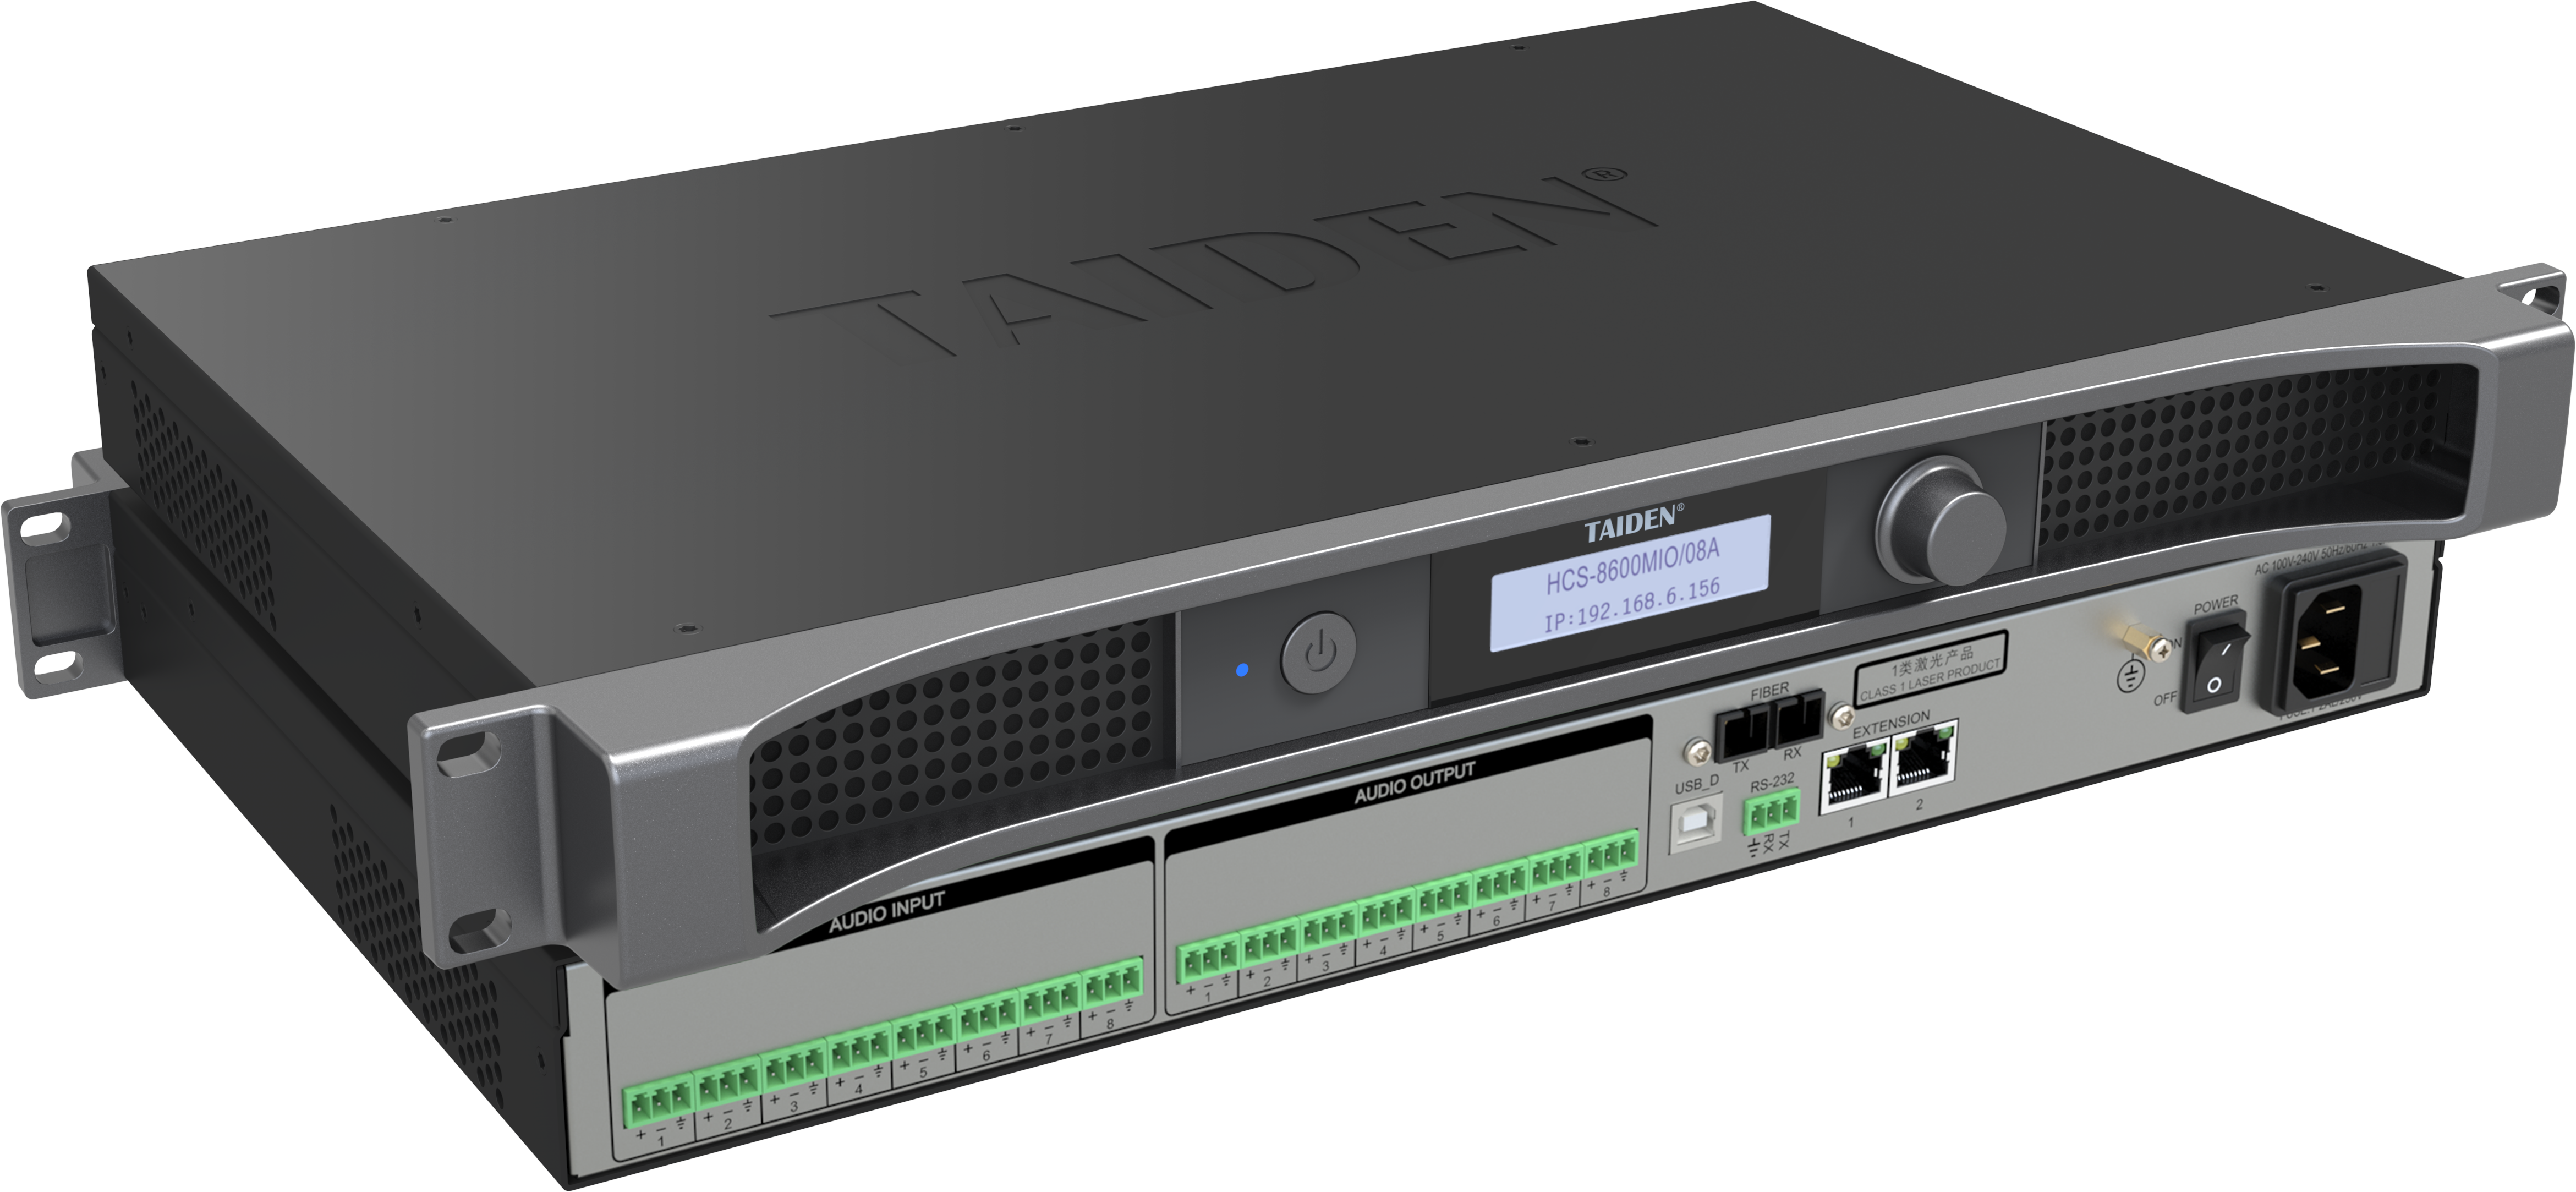
From here, two principles matter most: transparent signal flow and resilient distribution. Transparent flow means low-latency encoding, stable clocking, and predictable processing. Modern chains use lighter codecs tuned for speech, proper AES encryption, and synchronized DSP blocks to keep delay small and steady. Resilient distribution means dual-path networks with QoS and error correction, or well-planned infrared arrays that avoid dead zones. In practice, that could be hybrid: Dante or AES67 for backbone routing, with disciplined VLANs, and IR for audience receivers in high-density rooms. Interpreters benefit because their monitoring is clean; the audience benefits because packet loss or reflections do not tip the system over. When paired with smart interpreter equipment, operators can surface real alerts—overhead, crosstalk risk, or mis-matched sample rates—before they snowball.

Consider forward-looking control. Edge computing nodes at the venue can watch jitter and latency in real time, while a cloud dashboard aggregates event logs across sites. Operators can simulate failover, verify redundancy, and audit power budgets before doors open. Semi-formal teams gain a playbook: preflight tests, live observability, and graceful degradation if a switch or amplifier fails. The result is not magic; it is engineering discipline. Keep IR emitters mapped, RF kept clean, PoE switches sized for peak draw, and codec settings locked for speech. Do this well and the “translation problem” shrinks into routine AV work—reliable, repeatable, and calm.
Choosing Wisely: Three Metrics That Matter
To translate these insights into action, use three evaluation metrics. First, end-to-end latency under load: test the full chain, including DSP, codec, and distribution, and aim for stable delay with tight variance. Second, channel integrity at scale: measure crosstalk, RF noise, and IR coverage, and confirm intelligibility at the room’s edges (and behind pillars). Third, operational telemetry: require per-channel health, error logs, and simple failover—operators must see packet jitter, gain staging, and device status in one view. If a candidate platform nails these three, it will likely handle real shows, not just demos. When ready to map features to practice—and compare integrated systems to piecemeal stacks—review vendor documentation and run a live pilot with interpreters in the loop. That is how the audience hears the difference, and how teams earn trust across languages, day after day with TAIDEN.